AI crawlers / AI crawlers
ICC-Crawler: what it does and what blocking it changes
What ICC-Crawler is
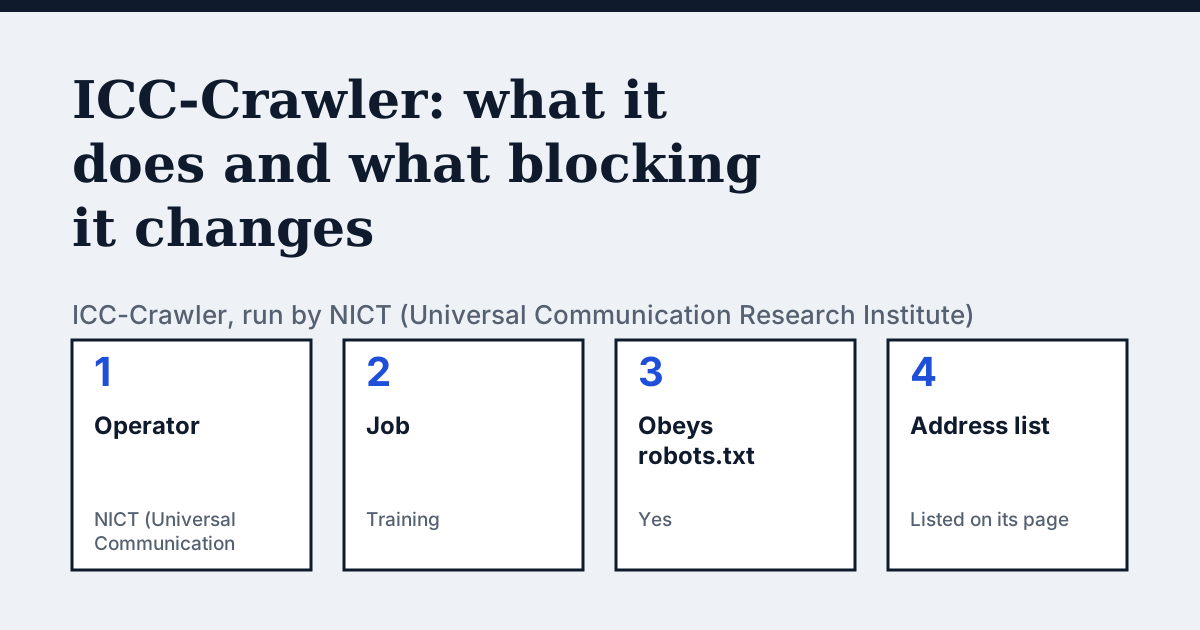
ICC-Crawler is a crawler run by the Universal Communication Research Institute at Japan's National Institute of Information and Communications Technology (NICT). NICT says it uses collected pages for research and development of information processing technologies, including multilingual translation, information analysis and artificial intelligence. NICT may also provide collected information or research products to third parties, to the extent permitted by law.
| Fact | ICC-Crawler |
|---|---|
| Operator | NICT (Universal Communication Research Institute) |
| Job | Research data collection (includes AI research and development) |
| robots.txt token | ICC-Crawler |
| Follows robots.txt | Yes, and with a Crawl-Delay it uses the larger of that interval and its own minimum |
| IP addresses | Listed on the vendor's page (ucri.nict.go.jp/en/icccrawler.html) |
| Vendor page read | 24 October 2026 |
What the vendor says
In the vendor's words (English original): “NICT uses the information it collects for research and development of advanced information processing technologies including multilingual translation, information analysis, and artificial intelligence technologies.”
Source: NICT Universal Communication Research Institute: ICC-Crawler, read on 24 October 2026.
What happens if you block ICC-Crawler
NICT says ICC-Crawler supports the Robots Exclusion Protocol and that adding User-agent: ICC-Crawler with Disallow: / to robots.txt could disable collection from all pages. It also lets site owners block a path or file type, or allow selected paths under a full Disallow. If access continues after that, NICT asks site owners to contact it so it can stop collecting from the host.
The robots.txt lines
To allow ICC-Crawler:
User-agent: ICC-Crawler
Allow: /
To block ICC-Crawler:
User-agent: ICC-Crawler
Disallow: /
Paste a block into the robots.txt at the root of your host, for example https://example.com/robots.txt. A group for one token does not cover the operator's other crawlers.
The vendor's page shows no full user-agent string for ICC-Crawler.
How to tell a real request from a fake one
The vendor page lists the crawler's IP addresses in plain text; it does not publish a machine-readable list.
Compare with GPTBot
GPTBot: Both collect pages that feed AI development, but ICC-Crawler is run by a Japanese public research institute for its own research and publishes two crawler IP addresses on its page, while GPTBot is run by a commercial company.
Your own site
The free check in the box above tests eight crawlers (GPTBot, OAI-SearchBot, ChatGPT-User, PerplexityBot, ClaudeBot, Google-Extended, Bingbot and Googlebot). ICC-Crawler is not one of them: read your robots.txt for a ICC-Crawler group and look for the user agent in your server log. The full list of crawlers is on the AI crawler hub.
Questions people ask
Does ICC-Crawler follow robots.txt?
Yes, and with a Crawl-Delay it uses the larger of that interval and its own minimum. Give ICC-Crawler its own User-agent group in robots.txt: the operator's other crawlers have their own settings.
How do I know ICC-Crawler is really blocked?
robots.txt is only one layer: a CDN or firewall rule can also turn a crawler away, and a crawler can ignore the file. Check your server log for the user agent, and test the address from outside your network.
Sources
See what AI answers about your shop
The audit crawls your site up to your plan's page limit, shows which AI crawlers it lets in and gives the exact fix for each issue. From €9, 14-day money-back guarantee.
Audit my siteAudit from €9, paid once. 14-day money-back guarantee.