Guides / Crawlability
Is GPTBot blocked on my site? Four places to check, with a test for each
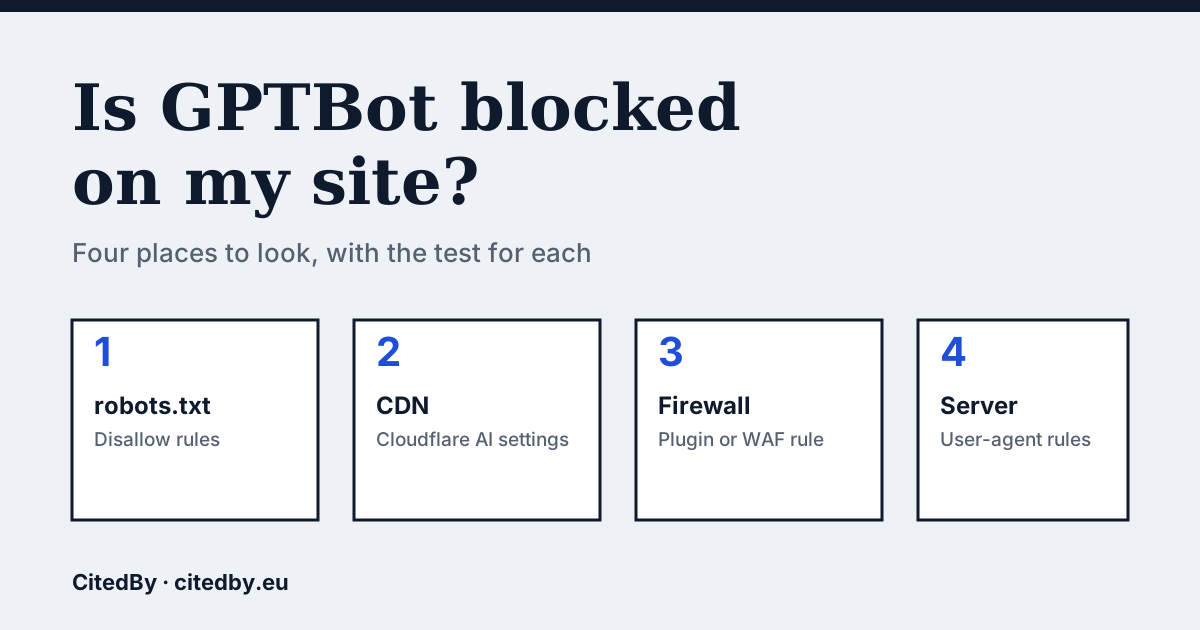
Four places GPTBot can be stopped
GPTBot is the crawler OpenAI says it uses to collect content that may be used to train its models. A request from it can be turned away at four layers, and each one needs its own test. The CitedBy audit in the box above covers the first. The other three answer with an error code even when robots.txt says yes.
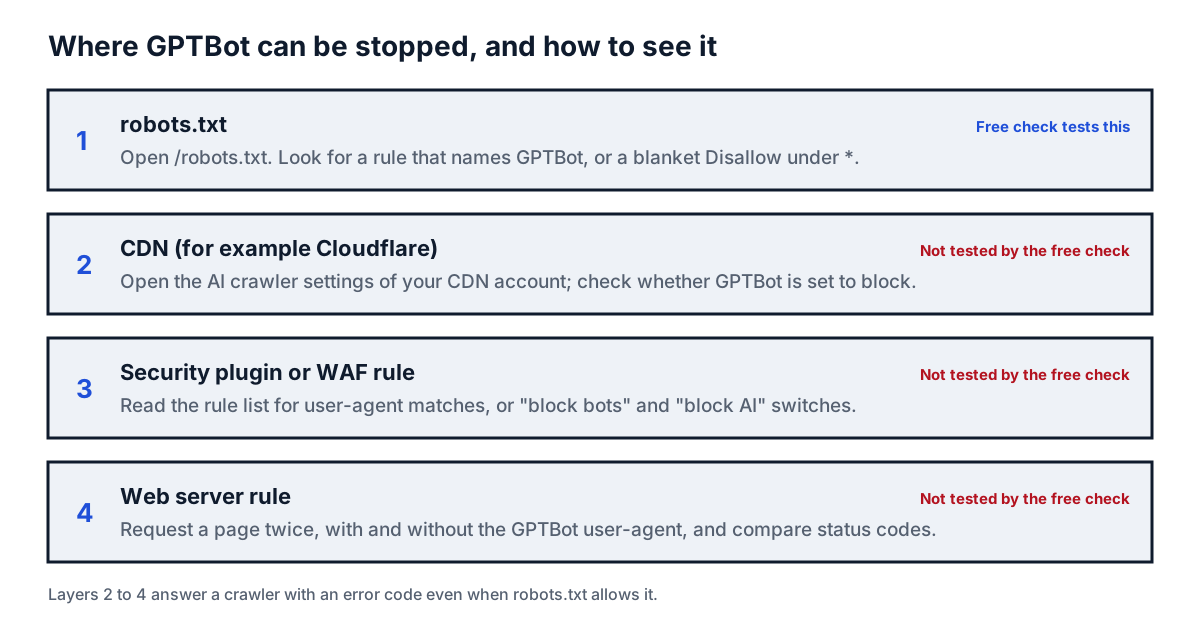
How to check, step by step
- Open
yourshop.com/robots.txtin a browser. Look for a group that namesGPTBot. If there is none, GPTBot follows theUser-agent: *group, so a blanketDisallow: /under it blocks GPTBot too (RFC 9309). - Audit your site with the box above (from €9). It reads robots.txt for GPTBot, OAI-SearchBot, PerplexityBot, Google-Extended and Bingbot and names the ones that are blocked.
- Send two requests to your homepage and compare the status codes: one normal, one that carries the GPTBot user-agent string. Commands below.
- Open your CDN account and look at its AI crawler settings. For Cloudflare, the steps are below.
- Open your security plugin or firewall rule list and search for
GPTBot,bot,AIandcrawler. - Search your server logs for
GPTBot. A run of 403 responses to it is the sign of a block that robots.txt does not show.
The two-request test
Replace yourshop.com with your address. The first command sends a normal request, the second sends the GPTBot user-agent string that OpenAI publishes. Each prints only the status code.
curl -s -o /dev/null -w "%{http_code}\n" https://yourshop.com/
curl -s -o /dev/null -w "%{http_code}\n" -A "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot" https://yourshop.com/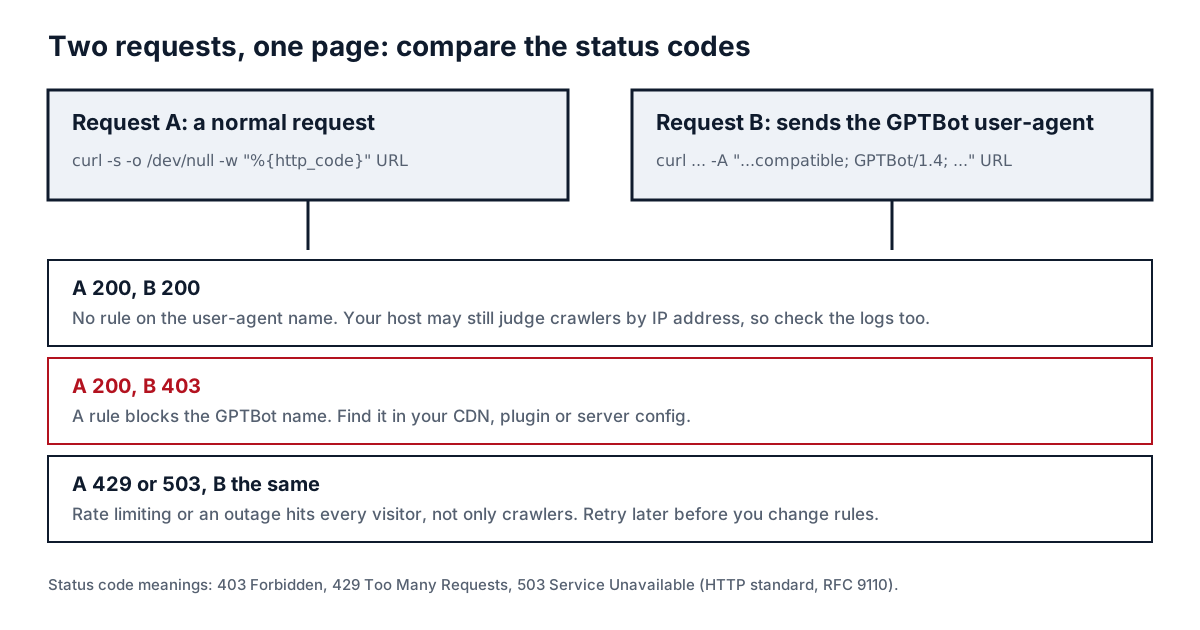
Read the result with one limit in mind. This test comes from your own computer. If your host also judges crawlers by IP address, the real GPTBot can get a different answer from the one you saw. OpenAI publishes the IP ranges for GPTBot at openai.com/gptbot.json, so your logs can show whether requests from those ranges got through (OpenAI crawler documentation).
Cloudflare: where the setting lives
Cloudflare's documentation describes the steps: open your domain, go to AI Crawl Control, open the Security tab, then the Crawlers tab. The Actions column lets you Allow or Block each crawler. Choosing Block creates or updates a WAF custom rule, and you can still enforce robots.txt when you choose Allow (Cloudflare: manage AI crawlers).
Cloudflare's defaults are also changing. Help Net Security reports that from 15 September 2026 new domains block Training and Agent crawlers by default on pages that show ads, while Search crawlers stay allowed (Help Net Security). Check your own dashboard rather than assuming which default your domain got.
When the check says your site refused the request
A plain request from our check can itself be refused. When the answer is HTTP 403, 429 or 503, the check says so and says it cannot tell from outside whether AI crawlers are refused as well. A 403 usually means a rule blocked the request. A 429 or 503 can also mean rate limiting or an outage, which affects every visitor. Fix the cause in your CDN, firewall or hosting panel, then run the check again.
Should you unblock GPTBot?
That is your decision, and blocking it is a legitimate choice. OpenAI lists GPTBot, OAI-SearchBot and ChatGPT-User as separate crawlers with separate jobs. GPTBot is for training data. OAI-SearchBot surfaces sites in ChatGPT's search features. ChatGPT-User fetches pages when a person asks about them.
| Your goal | What to do |
|---|---|
| Appear in ChatGPT search results, keep content out of training | Allow OAI-SearchBot, disallow GPTBot |
| Appear in ChatGPT search results and allow training | Allow both |
| Stay out of both | Disallow both and check your logs for ChatGPT-User |
A change to robots.txt can take about 24 hours to reach OAI-SearchBot, according to OpenAI.
Questions people ask
Does blocking GPTBot remove my shop from ChatGPT?
Not by itself. OpenAI describes OAI-SearchBot as the crawler for ChatGPT's search features and GPTBot as the training crawler, each set separately in robots.txt.
Why does robots.txt look fine but GPTBot still gets a 403?
robots.txt is a request to the crawler. A CDN, firewall or server rule can refuse the request anyway, so check those layers with the two-request test and your logs.
Does ChatGPT-User obey robots.txt?
OpenAI says robots.txt rules may not apply to ChatGPT-User, because a person starts those requests.
Will unblocking GPTBot get my shop recommended?
No. Being readable is the entry ticket. Whether an assistant names your shop depends on what it finds about your category, which the CitedBy audit measures with real buyer questions.
Sources
- OpenAI: crawlers and user agents, IP ranges
- Cloudflare: manage AI crawlers
- Help Net Security: Cloudflare changes AI crawler access rules, 2 July 2026
- IETF RFC 9309: Robots Exclusion Protocol
- CitedBy site audit
See what AI answers about your shop
The audit crawls every page of your site, shows which AI crawlers it lets in and gives the exact fix for each issue. From €9, 14-day money-back guarantee.
Audit my site